What Jev might mean to the legal world
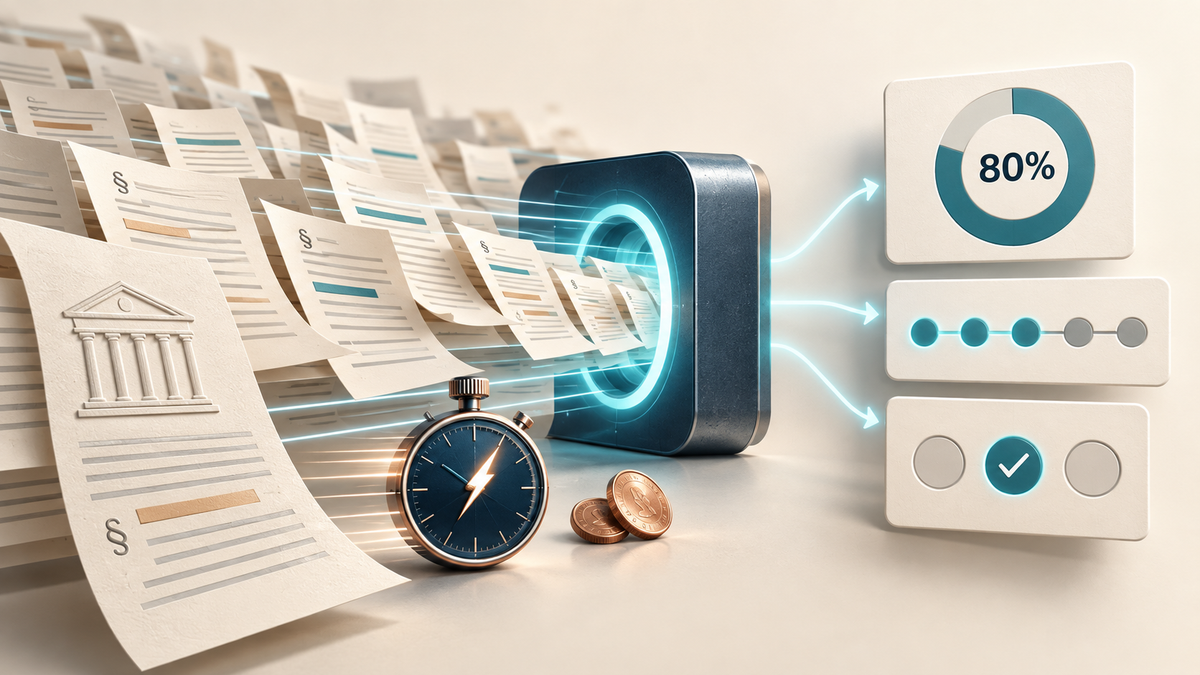
TypeSafe AI's new model answers closed questions about text in a fraction of a second and for almost nothing. If its accuracy holds up on legal material, which no one has yet shown, it could change how high-volume legal review is done.
Much legal work with documents consists of one small question asked many times. Is this email responsive to Request 14? Does this lease allow the tenant to assign without the landlord's consent? Did the citing court follow the earlier case or distinguish it? Did the plaintiff win?
Associates, contract reviewers and research assistants answer such questions by the thousands. For several years many have been handing them to generative language models. Those models have come to usually answer well, but in an odd way. The model writes its answer one token at a time, sometimes after paragraphs of reasoning. Software then parses the prose to recover what was, in the end, a yes or a no. At the scale of a document production that is slow and expensive. It also leaves the lawyer with an answer and no usable statement of how sure the model is.
On September 15, TypeSafe AI opened early access to a model called Jev. The company was founded by Diogo Almeida, formerly a researcher at OpenAI and a significant contributor to ChatGPT. Jev generates no text at all. Instead, it purports to be a fast, universal classifier. It has drawn a lot of attention over the past few days. Some of that attention is deserved.
Here is a Gemini notebook containing some of that publicity.
What Jev does
You give Jev a "state," meaning text plus whatever structured data you have, and one or more typed questions. There are three question types:
• a choice among up to 255 options you define
• a score on a scale you define
• a judgment from 0 to 1 on whether a statement is true
Jev returns the answer, a probability for each possible answer, and a confidence figure. Because it can only select from the answers you supplied, it cannot return anything outside them. TypeSafe describes this as being unable to hallucinate. That is accurate only in the narrowest sense: Jev can still select the wrong option.
The company says its training method rewards calibrated probabilities. If so, answers given 80 percent probability should be right about 80 percent of the time.
Touted virtues of Jev include speed and cost. TypeSafe reports responses in 70 to 500 milliseconds. A conventional large language model is likely to be 10 to 100 times slower. Jev's posted price is $0.042 per million input tokens, with no charge for output. A million documents of a thousand tokens each is a billion tokens, which comes to $42. The same thing on a large language model such as Claude or ChatGPT would well add two zeroes to the price total.
The company's demonstrations are a bot that plays Doom at ten decisions a second and a program that races through Wikipedia links. Neither is a legal task. Still, the design looks to me like a good match for a certain kind of legal work. You can feel the promise.
Legal tasks it might do well
Jev needs no labeled examples from your matter, because you define each category in words and the model already knows what the words mean. Somehow Jev has been trained on enough classification problems that it, like other forms of AI, can generalize to classification tasks it has never seen before. (Or at least that is the hope.) To be sure, general chat models do this too; they have been trained on enough language patterns so that they respond plausibly when they see language they have never seen before – yours. What is new here is the price and the probability attached to each answer. So, in theory, here are some important tasks on which Jev might be very useful. I am sure there are others.
First-pass document review. Jev could score every document for responsiveness and privilege and rank them by probability. That is what technology-assisted review already does, without first hand-coding a seed set.
Tabular review. Harvey, Legora and Hebbia sell this for due diligence. Documents are rows, questions are columns, and a model fills each cell. Jev answers many questions about one document in a single call, with little added delay. Per-cell confidence would let a reviewer sort the table so that the doubtful cells come first.
Midpage's research grid does the same thing with case law. One broad search supplies the rows, each research question becomes a column, and a column can be marked filterable so that only the cases meeting a stated criterion remain. That filter is a yes-or-no question put to every opinion in the result set, which is the kind of question Jev is built to answer, and a probability on each cell would tell the researcher which exclusions to check by hand. The other columns in Midpage, which summarize what a case says about an issue, are another matter. Jev cannot write a summary or pull a quotation, so there too the grid would be a hybrid.
Citators and docket monitoring. Classifying how each citing opinion treats an earlier case becomes cheap enough to run across the whole CourtListener corpus. So does sorting each new docket entry by type and significance.
There is a relationship between the Jev announcement and this week's news from Legora. Legora said it is building a full ontology of law and an AI-native citator: mapping how authorities relate, what each proposition means, the hierarchy of sources, and whether a rule is still good law, so its agents can research without the usual citation failures. That work is mostly graph-building and editorial QC.
The complementary slice is the millions of micro-judgments made along the way while building and using that graph:
- Holding versus dissent
- Whether a later case overrules an earlier one
- Whether a given memo is binding here
Each of these could probably be expressed as a typed Choice, Score, or Boolean question asked over document-plus-graph state. Jev, TypeSafe's new System One model, is built for exactly that: unstructured state in, calibrated classifications out, run in parallel, with no generated text. (Although it may well be that Legora, precisely for that reason, is not using LLMs for these parts of its ontology project.)
Ontology design still needs lawyers. Classifying each edge at corpus scale is the Jev-shaped job.
Checking generative output. Jev might also work as an inexpensive check on generative models. Pair each proposition in an AI-drafted brief with the passage cited for it, and ask whether the passage supports the proposition.
Cost matters as much as speed here because it decides what gets done at all. Review that costs thousands of dollars is done once, on the documents thought most important. At tens of dollars it can be done on everything, and redone whenever the questions change. The probabilities matter because they tell a lawyer where to spend her attention. Generative models have been poor at that.
Legal aid intake. A legal aid office could classify an intake narrative by practice area and urgency while the caller is still on the line.
Why I am a little Jev-skeptical
I have several concerns, and each is just a suspicion. I have not tested any of them.
No reasoning step. TypeSafe's documentation says questions should call for "the kind of judgment a highly knowledgeable person could make in a few seconds." Many legal judgments take longer. Deciding whether a change of control triggers a consent requirement can mean reading the assignment clause, a definition forty pages earlier, and an amendment. The documentation recommends breaking such a question into atomic questions and combining the answers in code. The legal reasoning then lives in the developer's decomposition. If the decomposition is wrong, no confidence score will show it. And the code that combines twenty atomic answers into one legal conclusion may itself be complicated, because the atoms interact: an exception swallows a rule, a definition changes what a clause covers, a later amendment overrides both. Writing that logic by hand is the very problem language models were built to spare us. So I am not confident that typing without reasoning will succeed in the many areas of law that turn on nuance. Generative models do not always succeed there either, but at least they try.
Limited to what it is given. There's a related problem. I found nothing in the documentation about retrieval, tool use or maximum input length. This version of Jev may be like the early versions of large language models. It apparently cannot call a tool, query a database or reach a connector of any kind. Whatever law it knows, it knows from its training data, and it cannot go and look anything up. That is notoriously hazardous in law, where the answer often depends on the fine print of a case the language model only encountered a few times in its training data, a statute amended last session, or a case decided last month. Maybe Jev 2.0 will have this capability. In the meantime, though, Jev is flying blind. Moreover, a long credit agreement may not fit in Jev's context window. These limitations make me wonder about how accurate Jev will be over a broad domain of legal materials and whether we will be able to trust Jev's asserted confidence in its own classifications.
No text output. Jev cannot return a party's name, a date, a liability cap, or the quoted language that supports its answer. Lawyers verify by reading the passage. A probability with no passage attached is hard to check and hard to defend. For that reason I expect tabular review built on Jev to be a hybrid, with some other model filling the text columns and locating the supporting passages.
Calibration may not carry over to legal material. Calibration matters enormously in law, because a lawyer who knows which answers to distrust can put her hours there, and one who does not must check everything or nothing. Most models say little about how sure they are, so it is genuinely good that Jev makes a serious attempt. But a stated probability is itself a claim that can be wrong. Calibration is measured against a particular mix of tasks. Good calibration on TypeSafe's tasks does not establish it for merger agreements, or for rare categories such as privileged documents. Anyone using Jev on a production would need the validation sampling that review protocols have required for more than a decade. Put differently, we would have to calibrate the calibrator: hand-code a sample, bin the answers by the probability Jev assigned them, and see whether the 80 percent bin is right about 80 percent of the time.
Categories defined in words. "Responsive" means whatever the document requests say it means. Terms of art shift from one jurisdiction to another. I saw no way to supply examples that fix a meaning, and I do not know how sensitive the answers are to the phrasing of the question.
Two practical points. The benchmark results come from evaluations TypeSafe wrote itself, and the company acknowledges that this may introduce bias. Jev also runs only on TypeSafe's servers, and I found no data-retention terms. Confidential client material should stay out for now.
A few hours after posting this blog entry, I received trial access to Jev. It's kind of bad news. I have examined the terms of service and privacy policy, and I have serious reservations about using Jev in representing a client or processing confidential information of any sort. They contain a welcome promise not to train on inputs but that is not going to be enough for attorneys or perhaps others handling sensitive data. The privacy policy contemplates disclosure when inputs contain undefined “objectionable content.” Lawyers routinely examine precisely that material: threats, discriminatory emails, evidence of fraud. Confidentiality concerns begin with the provider's authority to examine and use those communications, not merely its willingness to refrain from passing them along.
The customer agreement supplies confidentiality protections, but their interaction with the privacy policy needs clarification. Broad telemetry rights and indefinite retention compound the concern.
Jev needs to rethink these terms or offer alternatives if it wants to enter the legal and corporate markets. Its toy examples about whether hotdogs are sandwiches are fun (They are, 58%). That will not cut the mustard, however, it when the input is a client's confidential internal investigation.
Why legal educators should pay attention
But still there is that promise! Here are a few things that might become possible if Jev proves out. I am confident I am neglecting many others.
Empirical scholarship. Hand-coding variables for a few hundred opinions now takes months or more of research-assistant time. Trust me. A generative model might already do that job almost as well as humans, and for a sample of that size cost is probably not the obstacle. Two things would change with Jev. Far larger datasets becomes affordable to code. And every coded variable arrives with a probability, so a scholar can weight observations, set aside the doubtful ones, or model her measurement error instead of ignoring it. That is what an LLM's verdict in prose does not easily provide.
Feedback on student work. A model could score a practice essay against each rubric item, such as whether the student saw the state action problem. Speed and cost are not the issue here; a generative model handles a class's worth of essays cheaply, and it can explain to the student why she missed state action, which Jev cannot. What Jev adds is a confidence score on each rubric item, so the professor can review only the ones the model was unsure about.
I said Jev might portend a new class of models for law, and I mean the hedge. I am eager to get my hands on it and find out. And even if this first version has the problems I suspect, that tells us little about the second or third, or about the competitors a good idea tends to attract. The history of language models is a warning against judging an idea by its first implementation. Jev is indeed an intriguing idea.
Notes
1. At the time I wrote this blog entry, I had not yet used Jev. Access is by waitlist, so most of what is here comes from TypeSafe's announcement and documentation. Again, right after I posted I received trial access. I hope to have hands-on information in a few days.
2. TypeSafe has not said how Jev was trained. I suspect it learned from a very large variety of question-and-option tasks, so that it acquired the general skill of matching text to a category described in words. Instruction-tuned models generalize in much the same way. Some of those tasks may have been answered first by larger models that reason at length. That is a guess.
3. The idea that tabular review should not rest on generative models is not mine. The legal AI company Isaacus has made that argument and built a version using models that extract spans of text from the source document, which Jev does not do.